
This article walks you through the steps to convert an existing Post Ingestion hook script to a workflow Bash Script.
Post Ingestion Hook
The Post Ingestion Hook feature allows you to run a script for specific tables/all tables in a table group after an ingestion job is completed. This functionality has been deprecated in the DataFoundry on Databricks product, in favour of Bash Script functionality in Orchestrator.
Bash Script
The Bash Script node in a workflow is a general purpose script executor and gives users more power to control the overall execution and orchestration of any DataFoundry workload.
Procedure
Post Ingestion Hook scripts can be executed at a table level but workflow Bash scripts can be executed only at a workflow level. Following are the steps that you can add to the script to make it work with Bash node:
Workflow Creation: Create a workflow with the Bash Scripts node after the Ingest Source node, allowing the script to be run after the ingestion of the table group. All the jobs in production must be of this type.
Script Changes: Following are the steps for the script to obtain the table details, so that the core logic of the script can be run for these tables: Obtaining Job ID from the Ingest Source node of the Workflow and Obtaining List of Tables and Status for Jobs.
Obtaining Job ID from the Ingest Source node of the Workflow
Obtain the job ID from the Ingest Source node of the workflow, that was part of the particular workflow run, so that it can be used to fetch and iterate through the list of tables, and obtain metadata like status, row count, etc.
Inputs
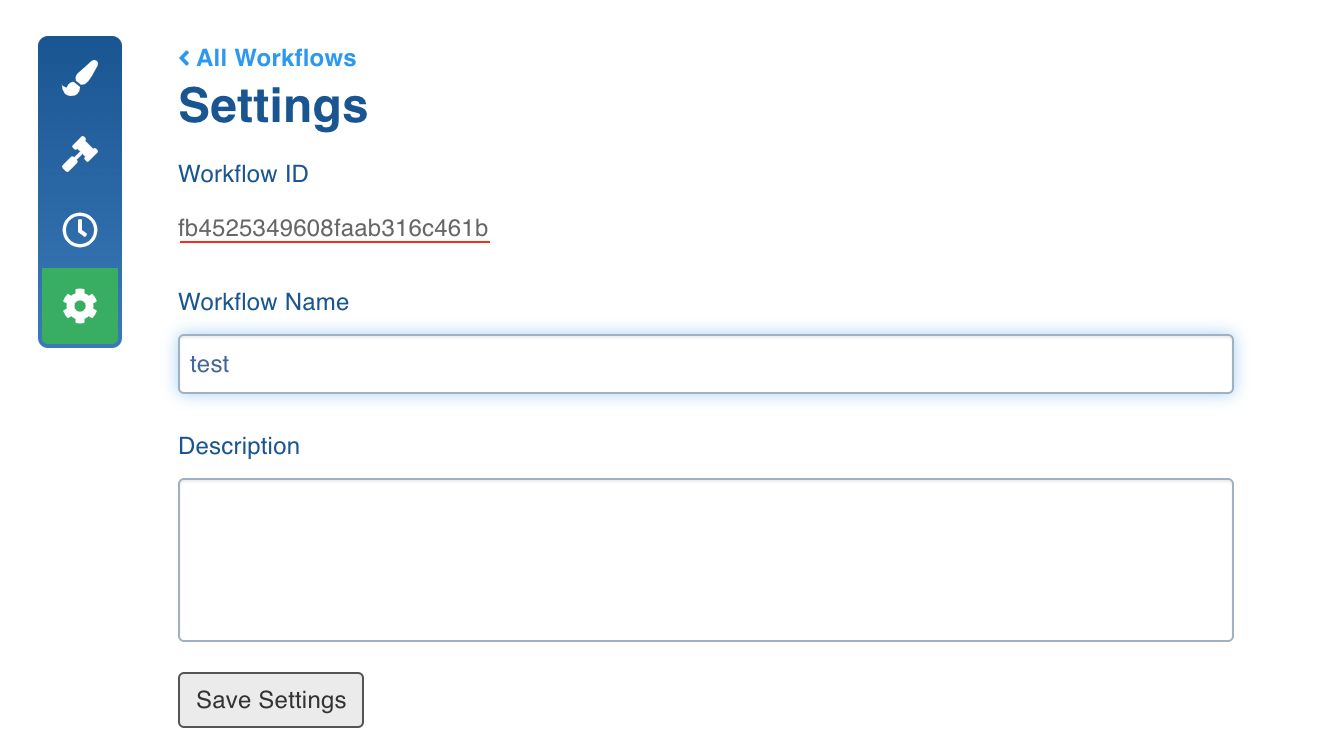
workflow_id: The ID of the workflow where the script will be run. This ID can be obtained from the Settings page for the workflow in the User Interface.
run_id: The run_id of the workflow can be accessed from the
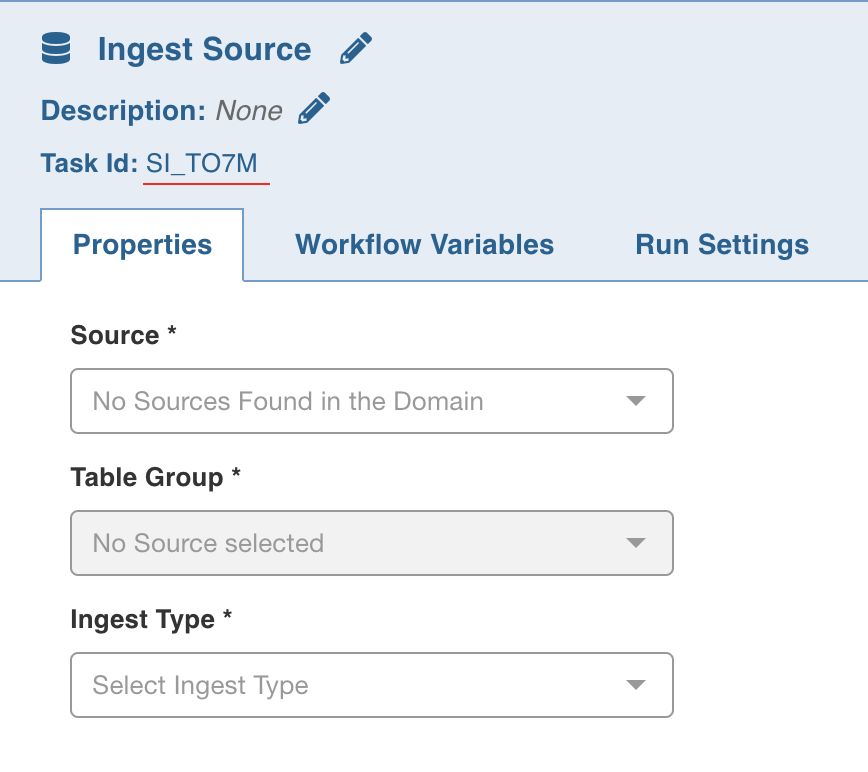
IW_WF_RUN_IDenvironment variable (os.getenv(‘IW_WF_RUN_ID’) or $IW_WF_RUN_ID in Bash)in Python).task_id: The task ID of the Ingestion Source task required to identify the workflow. This ID can be obtained by double-clicking on the task node in the User Interface.
API
Refer the following link for the workflow run variables: http://archiveddocs.infoworks.io/versions/3.2/infoworks_rest_api/workflow.html#get--v1.1-workflow-run-variables.json
Example Run
Output
In the response for the API, you can obtain the job_id in the variables section for the Ingest Source Node task ( the task_id will remain constant and can be obtained from the UI).
Obtaining List of Tables and Status for Jobs
Obtain the list of tables and status for the jobs. Once you obtain the job ID, you can use the ingestion metrics API to get additional metadata to make decisions/perform required actions.
API
You can use the following API: http://archiveddocs.infoworks.io/versions/3.2/infoworks_rest_api/source.html#get--v1.1-source-ingestion-metrics.json
Example
Output
In this particular API, you can iterate through the result and obtain the table_id of each table in the job and obtain the desired metadata. For example, the status of ingestion can be determined by reading the ingest_status flag. By reading this flag, you can perform any action based on the previous job success or failure.